
Yearly Archives: 2019
Visiting the FACOM 128B 1958 Relay Computer
If you study the history of computing you might have heard of the FACOM 128B, a Japanese relay computer from 1958. It holds the distinction of being a contender for the oldest computer that still works in its original form, as it resides in a Fujitsu building in Numazu Japan. [CuriousMarc] visited the old computer and created a video about it as well as painting a picture of other contemporary machines. You can see the video below.
[Marc] explains how a relay machine was already behind the times in 1958, and also shows how the 5,000 relay machine is laid out. The machine on display came from a Tokyo university and did the kind of computations you might use a computer for today to do engineering design.
Watching — and hearing — the beast run a program to add three and three is very illustrative. The keyboards reminded us of old adding machines. The machine uses floating point or bi-quinary that stores each digit as 7 bits. This led to a wide word width but made it simple to see when a relay got stuck since each number had two parts and only one relay was on in each part for any number.
The video isn’t just a home movie of the visit but shows how the operator entered data and instructions along with how to read the output display. The machine had 180 words of memory that took several cabinets. That works out to about 13K of memory. That was still enough to set up the solution for a 5×5 matrix inversion. We were amused to see that a program loop was literally a loop of punched tape.
We like flying a jet plane but are nostalgic for airships. By the same token, we kind of wish our desktop computer used relays like this. We’d probably be pretty unhappy if either of those were really true. Then again, we have seen a single board relay computer recently.
We’ve actually seen this computer in an earlier post. There we noted the computer was asynchronous, something that would be unusual in a modern CPU.
source https://hackaday.com/2019/12/06/visiting-the-facom-128b-1958-relay-computer/
r/ProRevenge – Insecure Boss Tries To Fire Me! I Play UNO Reverse On Him! #youtubevids
THE MEGA YACHT PUZZLE! Raft Survival S2 Episode 3 #youtubevids
The Psychopath | House M.D. #youtubevids
Christian caller argues against same-sex marriage #youtubevids
r/IDontWorkHereLady – Really, I Don’t Work Here Anymore! #youtubevids
Behind Amazon’s Doors is a Library
Some people love Amazon, while others think it has become too big and invasive. But you have to admit, they build gigantic and apparently reliable systems. Interestingly, they recently released a library of white papers from their senior staff called the Builder’s Library.
According to their blog post:
The Amazon Builders’ Library is a collection of living articles that take readers under the hood of how Amazon architects, releases, and operates the software underpinning Amazon.com and AWS. The Builders’ Library articles are written by Amazon’s senior technical leaders and engineers, covering topics across architecture, software delivery, and operations. For example, readers can see how Amazon automates software delivery to achieve over 150 million deployments a year or how Amazon’s engineers implement principles such as shuffle sharding to build resilient systems that are highly available and fault tolerant.
The Amazon Builders’ Library will continue to be updated with new content going forward.
Right now there are only two topic areas: Architecture and Software Delivery/Operations. There are however a number of papers in each topic. For example, “Challenges with Distributed Systems” gives an overview of best practices for building systems with multiple computers.
Other papers cover things such as leader election, load shedding, and effective caching. Overall, it looks like a lot of interesting reading.
Amazon is into a dizzying array of services these days, ranging from satellite ground stations to oddball ways to deliver your latest coffee mug.
source https://hackaday.com/2019/12/06/behind-amazons-doors-is-a-library/
Inkjet Printing On The Cheap With A Continuous Ink System
Inkjet printers are cheap to buy, but expensive to run. Replacement cartridges can easily cost double the price of the hardware itself, leading many to decry the technology entirely. However, the hackers of the world have the problem licked – enter the continuous ink system.
[cprossu] wanted an affordable color printing solution for the hackerspace. A cheap printer was sourced from a thrift store. The model chosen was selected for its lack of cartridge DRM and the availability of kits on eBay for conversion to a continuous ink system. This involves running large refillable tanks of ink instead of small individual cartridges which must be thrown away when empty.
[cprossu] discusses both the challenges you’ll likely face in a general build, as well as the specific work required to handle the conversion on an Epson Artisan 725. There’s also excessive label-maker abuse, which always brings a smile to our face. It’s a conversion well worth considering if you find yourself regularly purchasing expensive cartridges. We’ve even seen similar builds as far back as 2009, right from the ground up!
source https://hackaday.com/2019/12/06/inkjet-printing-on-the-cheap-with-a-continuous-ink-system/
Swapping the ROMs in Mini Arcade Cabinets
You’ve probably seen a few of these miniature arcade games online or in big box retailers: for $20 USD or so you get scaled-down version of a classic arcade cabinet, perfect for a desk toy or to throw up on a shelf as part of your gaming collection. Like any good Hackaday reader, you were probably curious about what makes them tick. Thanks to [wrongbaud], we don’t have to wonder anymore.
Over the course of several blog posts, [wrongbaud] walks readers through the hardware and software used in a few of these miniature games. For example, the Rampage cabinet is using a so-called “NES on a Chip” along with a SPI flash chip to hold the ROM, while Mortal Kombat is using a Genesis emulation solution and parallel flash. It wouldn’t be interesting if they didn’t throw you a few curves now and again, right?
 But these are more than simple teardowns. Once [wrongbaud] gives an overview of the hardware, the next step is reading the respective flash storage and trying to make sense of the dumped data. These sort of games generally reuse the hardware among a number of titles, so by isolating where the game ROM is and replacing it, they can be made to play other games without hardware modification. Here, this capability is demonstrated by replacing the ROM data for Rampage with Yoshi’s Cookie. Naturally it’s one of those things that’s easier said than done, but it’s an interesting proof of concept.
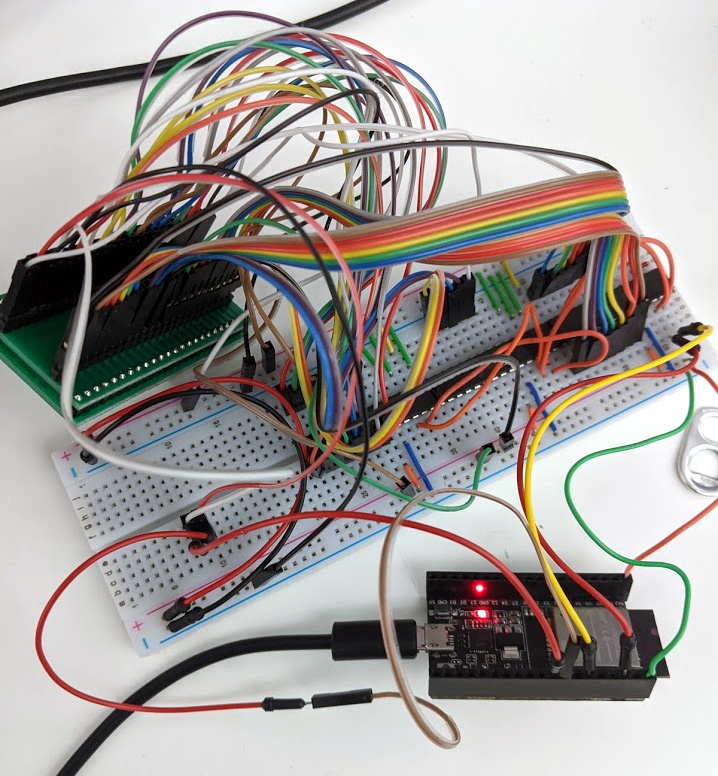
The Mortal Kombat cabinet is a newer addition to the collection, so [wrongbaud] hasn’t progressed quite as far with that one. The parallel flash chip has been dumped with the help of an ESP32 and a MCP23017 I/O expander, and some Genesis ROM headers are identifiable in the data, but there’s still some sifting to be done before the firmware structure can be fully understood.
Even if you’re not in the market for a diminutive arcade experience, the information that [wrongbaud] has collected here is really phenomenal. From understanding protocols such as I2C and SPI to navigating firmware dumps with a hex editor, these posts are an invaluable resource for anyone looking to get started with reverse engineering.
source https://hackaday.com/2019/12/06/swapping-the-roms-in-mini-arcade-cabinets/
David Williams Is “FPGA-Curious”
If you hadn’t noticed, we had a bit of an FPGA theme running at this year’s Superconference. Why? Because the open-source FPGA toolchain is ripening, and because many of the problems that hackers (and academics) are tackling these days have become complex enough to warrant using them. A case in point: David Williams is a university professor who just wanted to build a quadruped robotics project. Each leg has a complex set of motors, motor drivers, sensors, and other feedback mechanisms. Centralizing all of this data put real strains on the robot’s network, and with so many devices the microcontrollers were running out of GPIOs. This lead him to become, in his words, “FPGA-curious”.
 If you’re looking for a gentle introduction to the state of the art in open-source FPGAs, this is your talk. David covers everything, from a bird’s eye view of hardware description languages, through the entire Yosys-based open-source toolchain, and even through to embedding soft-CPUs into the FPGA fabric. And that’s just the first 18 minutes. (Slides for your enjoyment, and you can watch the talk embedded below the break.)
The second half of the talk is more about his personal experience and advice based on the last year or so of his experience going from FPGA newbie to master of his own robot. He highlights the versatility of a soft-CPU in an FPGA versus a pre-baked microcontroller solution. With the microcontroller you get all of the peripherals built into the silicon, but with the FPGA you get to write your own peripherals. Want a 10-wire SPI-like bus? Just code it up. Your peripherals are as simple or complex as you need them to be.
On the hardware side, David touts the PMOD standard (a man after our own heart!) and points out the large ecology of PMOD-compatible devices out there. Going for a plug-in solution also means that your engineering job is reduced to building a carrier board that can seat the FPGA brainboard of your choosing and interface it with a bunch of PMODs. It’s hard to get much simpler than that.
David is very much interested in the software layer as well, and encouraging re-usability of Verilog code among designs. Towards this end he’s written his own bus and interconnect standard, and a few modules that do things such as buffer data, process video, and so on. While we would have probably gone for the open-source standard WISHBONE interconnect architecture, David bundled a bunch of the possible signals together and called it a “pipe”. Compared to WISHBONE, David’s design makes a few judicious choices and thus streamlines interconnection greatly. He has code to go with it all, so have a look if you’re interested. We’re just speculating, but if you wrote a “pipe” to WISHBONE connector, you’d have the best of both worlds.
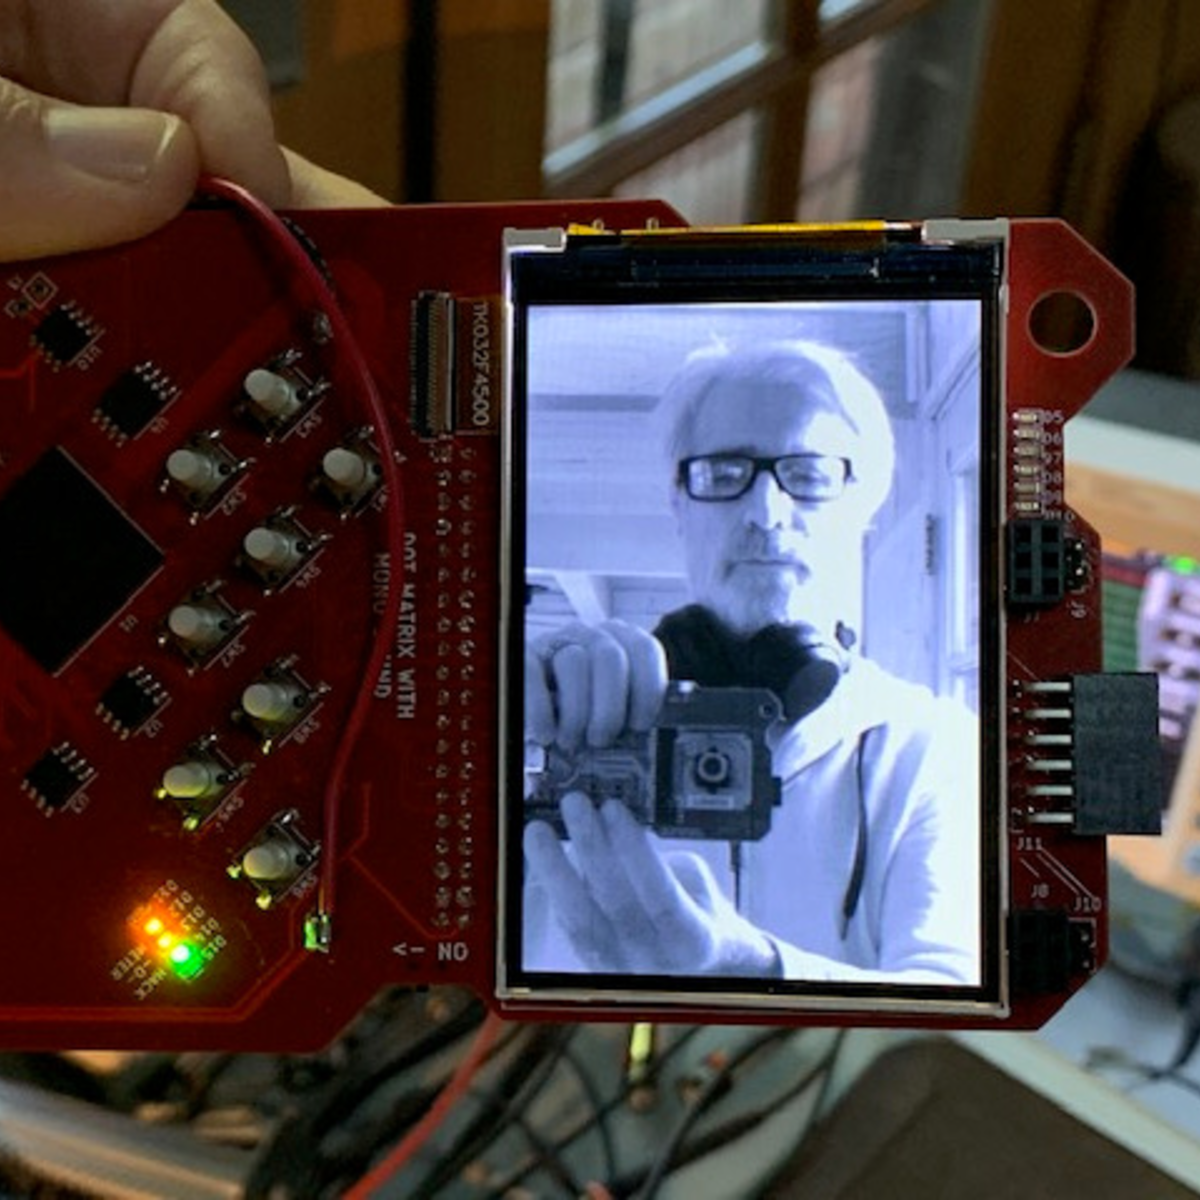 Finally, David isn’t just whistling Dixie. He took a video camera, plugged it into his Supercon badge via the cartridge slot, and had it displaying video in real time, all of this using pieces of code that he’d previously written and simply connected together with his “pipes”. A great demo is very convincing.
In sum, David’s talk is a great summary of the state of play in open-source FPGAs right now. Whether you’re getting your first taste, or are a moderately skilled FPGA developer, there is something for you here. And if anything, David’s call to end the fifty years of secrecy and IP-hoarding that have surrounded FPGAs is a rallying cry that we can get behind. We’ve gotten the tools in our hands now, and the hardware has become cheap and accessible. If you’re looking for a place to start, try the self-guided FPGA workshop from Supercon, and then maybe Al Williams’ FPGA Bootcamp. The time for a hacker FPGA revolution is ripe. To arms!
source https://hackaday.com/2019/12/06/david-williams-is-fpga-curious/
Chandrayaan-2 Found by Citizen Scientist; Reminds Us of Pluto Discovery
What does Pluto — not the dog, but the non-Planet — have in common with the Vikram lunar lander launched by India? Both were found by making very tiny comparisons to photographs. You’d think landing something on the moon would be old hat by now, but it turns out only three countries have managed to do it. The Chandrayaan-2 mission would have made India the fourth country. But two miles above the surface, the craft left its planned trajectory and went radio silent.
India claimed it knew where the lander crashed but never revealed any pictures or actual coordinates. NASA’s Lunar Reconnaissance Orbiter took pictures several times of the landing area but didn’t see the expected scar like the one left by the doomed Israeli lander when it crashed in April. A lot of people started looking at the NASA pictures and one Indian computer programmer and mechanical engineer, Shanmuga Subramanian, seems to have been successful.
According to Shanmuga and NASA, he looked at the last known position and velocity and used it to estimate where there might be debris. A white spec about a kilometer away from the proposed landing site wasn’t there on earlier images of the same area. NASA received the report of the suspected finding and confirmed it along with finding a spray of debris.
Is It or Isn’t It?
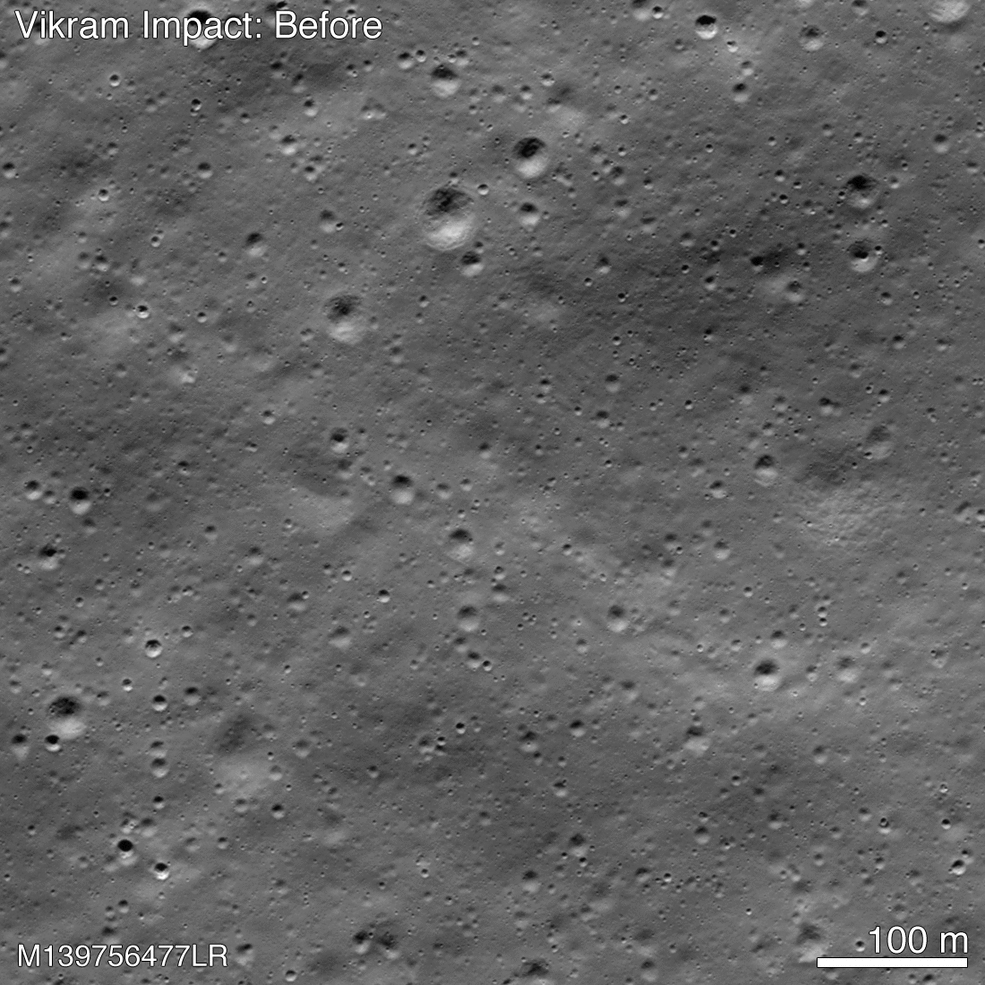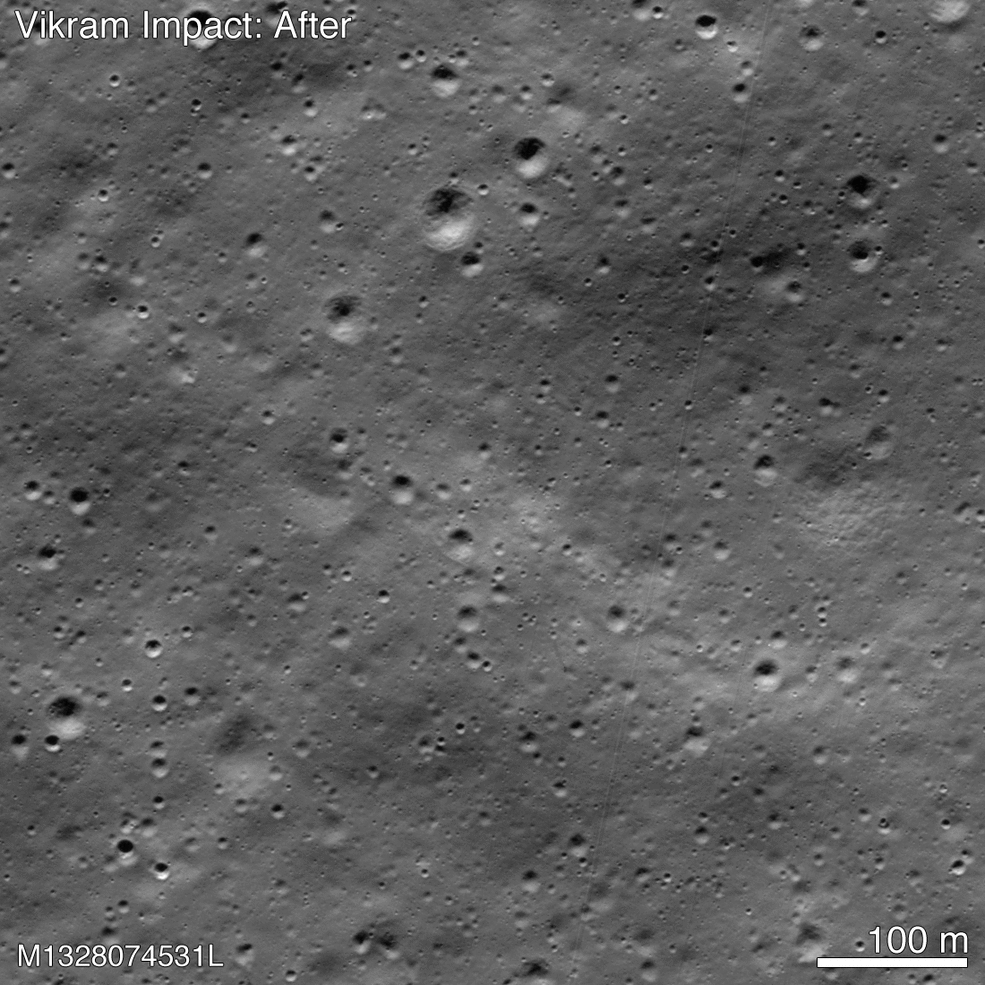
According to NASA, the camera resolution is about 1.3 meters per pixel and the largest debris is about two square pixels. The Indian Space Research Organization (ISRO) claims they already knew where the lander crashed. On the other hand, a senior ISRO official has cast doubt on the NASA images, although he points out he is stating his personal views. Still, you’d presume if they know where it is, they would know for sure if the NASA analysis is correct or not.
See For Yourself
NASA has a great before and after image that shows the difference very clearly. You can see it below:
Pluto in a Blink
This couldn’t help but remind me of how Pluto was discovered using a machine called a blink comparator. This machine dates back to 1904 and — like many things — has been superseded by modern technology. In 1930, scientists knew there was something pulling the orbits of the planets but they didn’t know where it was.
The blink comparator helps you find something that moves by showing you two photographic plates in quick succession. Anything in the same spot on both plates appears stationary. Anything moving in the frame will stand out as it appears to jump from one spot to another.
In 1906, Percival Lowell started searching for “Planet X” in earnest. He died ten years later never knowing that he had photographed Pluto twice in 1915 but failed to notice it. Retrospectively, there were at least 14 other photographs of the quasi-planet that no one noticed at the time, going back to 1909.
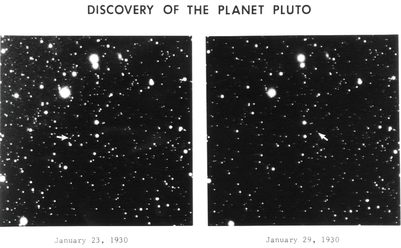 In 1929 — after a lot of legal battles between the Lowell Observatory and Lowell’s widow, the search resumed with Clyde Tombaugh given the task as something suitable for a young astronomer. Tombaugh took pictures of the night sky in pairs and used a blink comparator to see if anything moved. He had a 13″ telescope — respectable, but not huge by today’s standards.
The discovery came out in March of 1930. Did you know that since then Pluto still hasn’t made it all the way around the sun? A year on Pluto is nearly 250 Earth years long. You can see more about the comparator at the Lowell Observatory in the video below.
Modern Science
While Tombaugh wasn’t technically a citizen scientist, we have access to tools he couldn’t dream of. While blink comparators are a thing of the past, we have a whole arsenal of digital imaging tools along with large numbers of images from ground-, space-, and vehicle-based telescopes and cameras. We applaud Shanmuga Subramanian for making use of these tools so successfully.
You can even do observations with a crowd if you like. You can also use some pretty big scopes online. Meanwhile, good luck to ISRO with their third mission, coming soon.
Hackaday Podcast 045: Raspberry Pi Bug, Rapidly Aging Vodka, Raining on the Cloud, and This Wasn’t a Supercon Episode
Hackaday editors Mike Szczys and Elliot Williams talk over the last three weeks full of hacks. Our first “back to normal” podcast after Supercon turns out to still have a lot of Supercon references in it. We discuss Raspberry Pi 4’s HDMI interfering with its WiFi, learn the differences between CoreXY/Delta/Cartesian printers, sip on Whiskey aged in an ultrasonic jewelry cleaner, and set up cloud printing that’s already scheduled for the chopping block. Along the way, you’ll hear hints of what happened at Supercon, from the definitive guide to designing LEDs for iron-clad performance to the projects people hauled along with them.
Take a look at the links below if you want to follow along, and as always tell us what you think about this episode in the comments!
Direct download (71 MB)
Places to follow Hackaday podcasts:
Episode 045 Show Notes:
New This Week:
Interesting Hacks of the Week:
- Raspberry Pi 4 HDMI Is Jamming Its Own WiFi
- Core XY Explained
- Aging Alcohol In 30 Minutes
- Mike Harrison Knows Everything About LEDs
- DIY Photo Backup In The Field
- Print From The ESP8266, Courtesy Of Google
Quick Hacks:
- Mike’s Picks:
- Elliot’s Picks:
Can’t-Miss Articles:
Tuning Up the ThinkGeek Star Trek Intercom Panel
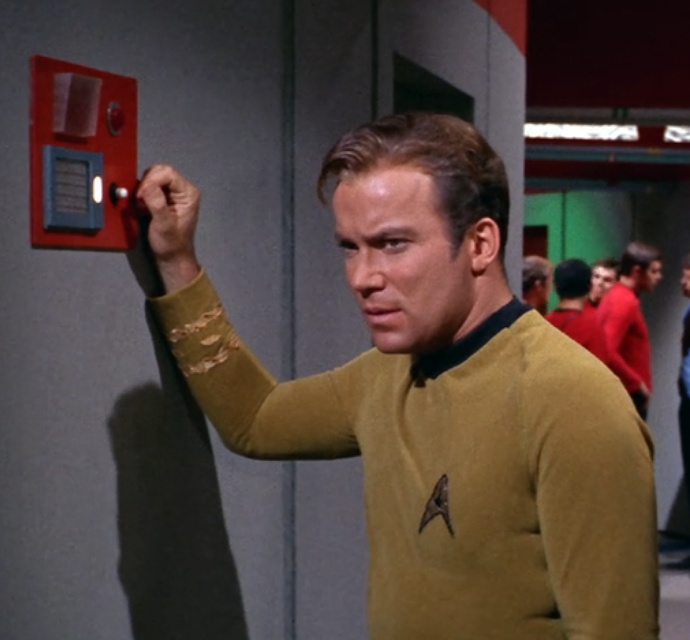
On Star Trek, all Kirk and friends had to do was snap the button on the always conveniently located intercom panel, start talking, and the intended recipient would immediately respond no matter where they were in the ship. How did it work? Who knows. In spite of, or perhaps even because of, the lightly-explained nature of the technology, the cherry-red wall intercoms still hold a certain charm for fans of the groundbreaking show.
A viewer sent [Fran Blanche] a scaled down replica of the intercom from ThinkGeek, and while it certainly looks fairly close to the original prop, it has a couple of annoying design elements. When triggered by the side-mounted motion sensors, the panel will play either the iconic swoosh of the automatic doors or the “Red Alert” sound effect. It’s a cute idea for a kid’s bedroom maybe, but not exactly ideal for somebody who regularly records YouTube videos.
So the first order of business was to cut the motion sensors out of the circuit and replace them with a push button. [Fran] draws up a quick diagram to explain how these sensors work, and shows that they can easily be bypassed with a momentary switch since they normally bring the line high when triggered. She then converted the indicator light on the right side of the panel into a button to enable the alert sound effect, which is more accurate to how it worked in the show anyway.
The other issue, and perhaps the most egregious to Star Trek fans, is that the “Red Alert” indicator on the top of the panel didn’t actually flash like it did in the show. To design and build this panel and not put a few LEDs behind that piece of frosted plastic seems a bit like producing a Matchbox car and forgetting to make the wheels spin. With a couple of red LEDs and a bit of new wiring, the oversight was quickly rectified.
While it might not be perfect, at least ThinkGeek actually produced a functional product this time. It could have ended up like one of their April Fool’s “products” that never get put into production, forcing a desperate Trekkie to begrudgingly build his own version.
source https://hackaday.com/2019/12/06/tuning-up-the-thinkgeek-star-trek-intercom-panel/
A Newbie Can’t Take The Heat | House M.D. #youtubevids
I’m Creating the FANTASY LAPTOP CASE I Always Wanted! #youtubevids
This Week in Security: Tegra Bootjacking, Leaking SSH, and StrandHogg
CVE-2019-5700 is a vulnerability in the Nvidia Tegra bootloader, discovered by [Ryan Grachek], and breaking first here at Hackaday. To understand the vulnerability, one first has to understand a bit about the Tegra boot process. When the device is powered on, a irom firmware loads the next stage of the boot process from the device’s flash memory, and validates the signature on that binary. As an aside, we’ve covered a similar vulnerability in that irom code called selfblow.
On Tegra T4 devices, irom loads a single bootloader.bin, which in turn boots the system image. The K1 boot stack uses an additional bootloader stage, nvtboot, which loads the secure OS kernel before handing control to bootloader.bin. Later devices add additional stages, but that isn’t important for understanding this. The vulnerability uses an Android boot image, and the magic happens in the header. Part of this boot image is an optional second stage bootloader, which is very rarely used in practice. The header of this boot image specifies the size in bytes of each element, as well as what memory location to load that element to. What [Ryan] realized is that while it’s usually ignored, the information about the second stage bootloader is honored by the official Nvidia bootloader.bin, but neither the size nor memory location are sanity checked. The images are copied to their final position before the cryptographic verification happens. As a result, an Android image can overwrite the running bootloader code.
The simplest way to use this vulnerability is to replace the verification routine with NoOp instructions. The older T4 devices copy the Android image before the trusted OS is loaded, so it’s possible to load unsigned code as the Secure OS image. If you want to dig just a bit further into the technical details, [Ryan] has published notes on the CVE.
So what does this mean for the hobbyist? It allows for things like running uboot at the equivalent of ring 0. It allows running more recent Android releases on Tegra devices once they’ve been end-of-lifed. It might even be possible to load Nintendo Switch homebrew software on the Nvidia Shield TV, as those are nearly pieces of hardware. Hacks like this are a huge boon to the homebrew and modding community.
We’ve seen this before, and I suspect this style of vulnerability will show up in the future, especially as ARM devices continue to grow in popularity. I suggest this class of vulnerability be called Bootjacking, as it is a highjack of the boot process, as well as jacking instructions into the existing bootloader.
Leaky SSH Certificates
SSH certificates are a serious upgrade over simple passwords. So much so, services like Github and Gitlab have begun mandating SSH keys. One of the quirks of those services: Anyone can download public SSH keys from Github. When a client connects to an SSH server, it lists the keys it has access to, by sending the corresponding public keys. In response, if any of those keys are trusted by the server, it sends back a notification so the client can authenticate with the secret key.
[Artem Golubin] noticed the potential data leak, and wrote it up in detail. You could pick a developer on Github, grab his public SSH key, and start checking public-facing SSH servers to find where that public key is recognized. This seems to be baked into the SSH protocol itself, rather than just an implementation quirk. This isn’t the sort of flaw that can be turned into a worm, or will directly get a server compromised, but is an interesting information gathering tool.
HackerOne Exposed
HackerOne is a bug-bounty-as-a-service that represents a bunch of tech companies. Just recently they announced that a vulnerability had been found in the HackerOne infrastructure itself. A security researcher using the platform, [Haxta4ok00], was accidentally given an employee’s session key during a back-and-forth about an unrelated bug report, and discovered that session key allowed him to access the HackerOne infrastructure with the same permissions as the employee.
Session key hijacking isn’t a new problem; it is one of the attacks that led to the HTTPS everywhere approach we see today. Once a user has authenticated to a website, how does that authentication “stick” to the user? Sending a username and password with each page load isn’t a great idea. The solution is the session key. Once a user authenticates, the server generates a long random string, and passes it back to the browser. This string is the agreed upon token that authenticates that user for all further communication, until a time limit is reached, or the token is invalidated for another reason.
Not so long ago, most web services only used HTTPS connections for the initial user log-on, and dropped back to unencrypted connections for the bulk of data transfer. This session key was part of the unencrypted payload, and if it could be captured, an attacker could hijack the legitimate session and act as the user. The Firesheep browser extension made it clear how easy this attack was to pull off, and pushed many services to finally fixing the problem through full-time HTTPS connections.
HTTPS everywhere is a huge step forward for preventing session hijacking, but as seen at HackerOne, it doesn’t cover every case. The HackerOne employee was using a valid session key as part of a curl command line, and accidentally included it in a response. [Haxta4ok00] noticed the key, and quickly confirmed what is was, and that it allowed him access to HackerOne internal infrastructure.
The leak was reported and the key quickly revoked. Because it was leaked in a private report, only [Haxta4ok00] had access. That said, several other private vulnerability reports were accessed. It’s worth mentioning that HackerOne handled this as well as they could have, awarding $20,000 for the report. They updated their researcher guidelines, and now restrict those session keys to the IP address that generated them.
StrandHogg
One of the more notable stories in the past week was all about Android, and malicious apps masquerading as legitimate ones. StrandHogg has been exploited in one form or another since 2017, and was first theorized in a Usenix paper from 2015. In some ways, it’s an extremely simple attack, but does some very clever things.
So how does it work? A malicious app, once installed, runs in the background waiting for a target app to be launched. Once the target app is detected, the malicious app jumps to the forefront, disguised as the target. From here, a phishing attack is trivial. More interesting, though, is the permissions attack. Your benign application appears to request file system permissions, camera permissions, etc. It’s not immediately apparent that the malicious app is the one that is actually requesting permissions.
The only actual vulnerability here seems to be the ability of a malicious app to rename and “reparent” itself, in order to spoof being part of the target app. Do note that at least on permissions popups, the name of the requesting application is blank during a StrandHogg attack.
Contactless Payment
Contactless payments look like magic the first time you see them. Just wave a compatible card or mobile device over the payment terminal, and payment happens over NFC. Since you’re reading this column, it’s safe to assume that quickly after that first moment of awe wears off, you starting wondering how this is all done securely. That is what [Leigh-Anne Galloway] and [Tim Yunusov] wanted to know as well. They just released their research, and managed to find several nasty tricks. A tin-foil hat might be overkill, but maybe it’s time to invest in an NFC blocking wallet.
They manipulated data in transit, allowing for much larger payments without a PIN entry, made purchases via an NFC proxy, and even illustrated a practical pre-pay attack where a card could be read, make a fake transaction, and then play that fake transaction back for a real payment terminal.
Superfish returns?
Twitter is a fascinating place. Sometimes simple observations turn out to be CVEs. An interesting interaction took place when [SwiftOnSecurity] pointed out an odd DNS name, “atlassian-domain-for-localhost-connections-only.com”, with the description that it allowed a secure HTTPS connection to a service running on localhost. Our friend from Google’s Project Zero, [Tavis Ormandy], pointed out that a valid https cert installed on localhost means that Atlassian must be shipping a private certificate for that domain name as part of their software. Follow the link, and you too can host this oddball domain with a valid HTTPS certificate.
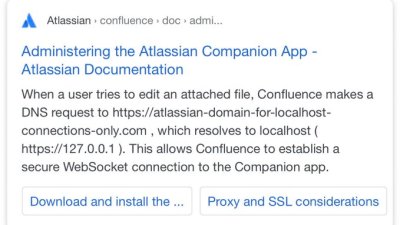
This is a bad idea for several reasons, but not the worst thing that could happen. The worst case scenario for this style of mistake probably belongs to Superfish. An aptly name adware program was pre-installed on many Lenovo machines in 2014, with the helpful feature of showing you more personalized ads. In order to do this, the software simply added its own certificate authority information to the system’s trusted CA bundle… and shipped the private certificate and key along with the software. Yes, you read that right, any HTTPS certificate could be perfectly spoofed for a Lenovo user.
Looking at the Atlassian domain, another user noted that IBM’s Aspera software had a similar localhost domain and certificate. According to [Tavis], that software also includes a full CA cert and key. If an iteration of IBM software actually added that CA to a system’s root trust, then it’s another superfish: Any HTTPS certification could be successfully spoofed.
source https://hackaday.com/2019/12/06/this-week-in-security-tegra-bootjacking-leaking-ssh-and-strandhogg/
Not-Quite-So-Hot Stuff: A Thermal Exam On The Latest Raspberry Pi
When the Raspberry Pi 4 was first launched, one of its few perceived flaws was that it had a propensity to get extremely hot. It’s evidently something the Pi people take very seriously, so in the months since they have addressed the problem with a set of firmware updates. Now they’ve taken a look at the effect of the fixes in a piece on the Raspberry Pi web site, and it makes for an interesting comparison.
The headline figure is that all updates together remove about a watt of power from the load, a significant quantity for what is still a board that can run from a capable phone charger. Breaking down the separate parts of the updates is where the meat of this story lies though, as we see the individual effects of the various USB, memory, power management and clocking updates. In temperature terms they measure an on-load drop from 72.1 °C to 58.1 °C, which should be a significant improvement for any Pi 4 owner.
There is a debate to be had over in what role a computer such as a Pi should serve. As successive revisions become ever more desktop-like in their capabilities, do they run the risk of abandoning the simplicity of a cheap Linux box as a component that makes us come back for more? It’s a possibility, but one they have very well addressed by developing the Pi Zero. They have also successfully avoided the fate of the Arduino — inexorably tied to its ATmega powered original line despite newer releases. As we have frequently said when reviewing Raspberry Pi competitors, it’s the software support that sets them apart from the herd, something this power-draw story demonstrates admirably.
source https://hackaday.com/2019/12/06/not-quite-so-hot-stuff-a-thermal-exam-on-the-latest-raspberry-pi/
House’s Stalker | House M.D. #youtubevids
Plywood!? What’s the worst that could happen? #youtubevids
Gameslab: The Other FPGA Game Console Badge
Anyone who was at Supercon will no doubt remember the badges that dangled around everyone’s neck. Some were reasonable, while some were neck-straining monsters that added anything and everything to hack the badge into something cool. We saw everything from AI cameras to a fully autonomous vehicle being worn with pride.
Sadly, one that we missed was Gameslab, [Craig J. Bishop]’s FPGA-based portable game console. No, not that FPGA-based game console; in an example of great minds thinking alike, [Craig] had actually been toying with his own handheld console design for quite some time. And we have to say the results are stunning.
The FPGA at the heart of this is a Xilinx Zynq FPGA-ARM Cortex A9 combo SoC, normally a prohibitively expensive monster of a chip. When [Craig] found “refurbished” Zynq chips on eBay for less than 10% of the cost of new units, it was literally game-on for the build. The console required a six-layer PCB to support the big BGA chip and the hundreds of support components around it. There’s a 5″ TFT touchscreen with a video controller implemented in the FPGA, a stereo sound system, and all the buttons and thumbsticks you’d expect on a modern console.
For our money, the best part is the case, about which [Craig] has yet to share any details. But it looks like a machined aluminum plate with wide chamfers around each cutout that contrast nicely with the brushed surface. We’ll be looking forward to more details on that and on progress with Gameslab.
source https://hackaday.com/2019/12/06/gameslab-the-other-fpga-game-console-badge/
House Gives Janitor A Promotion | House M.D. #youtubevids
A Magnetron Tear Down
Microwave ovens are everywhere, and at the heart of them is a magnetron — a device that creates microwaves. [DiodeGoneWild] tore one apart to show us what was inside and how it works. If you decide to do this yourself, be careful. The magnetron may have insulators made of beryllium oxide and inhaling dust from the insulator even one time can cause an incurable lung condition.
Luckily, you can’t get a lung problem from watching a video. In addition to just seeing the guts of the magnetron, there are also explanations about how everything works with some quick sketches to illustrate the points.
While we now think of a magnetron as a microwave oven component, they are important in many microwave devices including radar. They are interesting because all they can do is oscillate. You can’t use a magnetron as an amplifier (although it can pump a parametric amplifier). While they were instrumental in building compact and high-resolution radar during World War II, they have fallen out of favor today in that application because there are better alternatives. But there are over 1 billion magnetrons out in the wild, largely thanks to microwave ovens where the signal quality isn’t as important and the inexpensive construction is a big plus.
The beast has been around a long time, too, as an early form showed up in 1910. In 1925 there was a similar device but it topped out at 30 kHz. There was a time when the magnetron was top secret, but now you can make your own.
source https://hackaday.com/2019/12/05/a-magnetron-tear-down/