Cheap Current Probe Gets Good Review

A current probe isn’t a very common fixture on most workbenches because they are pretty expensive. [VoltLog] looks at a fairly inexpensive current probe from Micsig. He seemed impressed with the workmanship and it looks similar to more expensive offerings. There are two models with different bandwidth numbers (800 kHz and 2 MHz). It can measure current on a 10A and 100A scale.

According to [VoltLog] comparable probes from other vendors are more expensive and have lower bandwidth. He also liked that the device powers from USB since most newer scopes will have a USB port available.

If you aren’t familiar with a current probe, you might enjoy Digikey’s article on the topic or Keysight’s take on it. This probe can measure AC or DC current and while the specifications don’t promise super accuracy, [VoltLog] noted that his unit was better than the spec. He also noted that if you are wanting to measure small currents going to a microcontroller or similar device, these current probes are not really what you want to use.

We enjoyed the teardown of the device, too, about ten minutes into the video. The probe is surprisingly complex. It is possible that like some popular oscilloscopes, that changing the low bandwidth variant to the higher bandwidth model may be possible since the board appears to be used for both models.

We’ve looked at building very precise current probes. We’ve also looked at dirt cheap ones.

source https://hackaday.com/2020/09/26/cheap-current-probe-gets-good-review/

Tesla Turbine Boat Uses Lily Impeller

Typically in the RC community, radio control boats rely on small nitro engines or electric motors to get around. Fitted with traditional propellers, they’re capable of great speed and performance. Of course, there’s more than one way to skin a cat, as [Integza] shows with his latest build.

As far as the boat side of things is concerned, it’s a basic 3D printed single hull design. The innovation comes in the drivetrain, instead. The boat uses compressed air for propulsion, stored in a battery of four soda bottles, pressurized to 6 bar. The compressed air is used to drive a Tesla turbine of [Integza]’s design, which is 3D printed on a resin printer. Rather then driving a propeller, the Tesla turbine instead turns a Lily impeller, which pulls the boat through the water rather than pushing it along. The impeller uses a nature-inspired design, hence the name, and was also 3D printed, making producing its complex geometry a cinch. The guts of a toy radio control car are then used to control the boat.

Understandably, performance is less than stellar. The limited reserves of compressed air can’t propel the boat long, and the combination of the high RPM Tesla turbine and Lily impeller don’t provide a lot of thrust. However, the boat does move under its own power, demonstrating these oddball technologies while doing so.

[Integza] has been working with these technologies for a while; we featured an earlier Tesla turbine build back in 2018. Video after the break.

source https://hackaday.com/2020/09/26/tesla-turbine-boat-uses-lily-impeller/

Twitter: It’s Not the Algorithm’s Fault. It’s Much Worse.

Maybe you heard about the anger surrounding Twitter’s automatic cropping of images. When users submit pictures that are too tall or too wide for the layout, Twitter automatically crops them to roughly a square. Instead of just picking, say, the largest square that’s closest to the center of the image, they use some “algorithm”, likely a neural network, trained to find people’s faces and make sure they’re cropped in.

The problem is that when a too-tall or too-wide image includes two or more people, and they’ve got different colored skin, the crop picks the lighter face. That’s really offensive, and something’s clearly wrong, but what?

A neural network is really just a mathematical equation, with the input variables being in these cases convolutions over the pixels in the image, and training them essentially consists in picking the values for all the coefficients. You do this by applying inputs, seeing how wrong the outputs are, and updating the coefficients to make the answer a little more right. Do this a bazillion times, with a big enough model and dataset, and you can make a machine recognize different breeds of cat.

What went wrong at Twitter? Right now it’s speculation, but my money says it lies with either the training dataset or the coefficient-update step. The problem of including people of all races in the training dataset is so blatantly obvious that we hope that’s not the problem; although getting a representative dataset is hard, it’s known to be hard, and they should be on top of that.

Which means that the issue might be coefficient fitting, and this is where math and culture collide. Imagine that your algorithm just misclassified a cat as an “airplane” or as a “lion”. You need to modify the coefficients so that they move the answer away from this result a bit, and more toward “cat”. Do you move them equally from “airplane” and “lion” or is “airplane” somehow more wrong? To capture this notion of different wrongnesses, you use a loss function that can numerically encapsulate just exactly what it is you want the network to learn, and then you take bigger or smaller steps in the right direction depending on how bad the result was.

Let that sink in for a second. You need a mathematical equation that summarizes what you want the network to learn. (But not how you want it to learn it. That’s the revolutionary quality of applied neural networks.)

Now imagine, as happened to Google, your algorithm fits “gorilla” to the image of a black person. That’s wrong, but it’s categorically differently wrong from simply fitting “airplane” to the same person. How do you write the loss function that incorporates some penalty for racially offensive results? Ideally, you would want them to never happen, so you could imagine trying to identify all possible insults and assigning those outcomes an infinitely large loss. Which is essentially what Google did — their “workaround” was to stop classifying “gorilla” entirely because the loss incurred by misclassifying a person as a gorilla was so large.

This is a fundamental problem with neural networks — they’re only as good as the data and the loss function. These days, the data has become less of a problem, but getting the loss right is a multi-level game, as these neural network trainwrecks demonstrate. And it’s not as easy as writing an equation that isn’t “racist”, whatever that would mean. The loss function is being asked to encapsulate human sensitivities, navigate around them and quantify them, and eventually weigh the slight risk of making a particularly offensive misclassification against not recognizing certain animals at all.

I’m not sure this problem is solvable, even with tremendously large datasets. (There are mathematical proofs that with infinitely large datasets the model will classify everything correctly, so you needn’t worry. But how close are we to infinity? Are asymptotic proofs relevant?)

Anyway, this problem is bigger than algorithms, or even their writers, being “racist”. It may be a fundamental problem of machine learning, and we’re definitely going to see further permutations of the Twitter fiasco in the future as machine classification is being increasingly asked to respect human dignity.

source https://hackaday.com/2020/09/26/twitter-its-not-the-algorithms-fault-its-much-worse/

Linear Clock Ratchets up the Action

On the face of it, making a clock that displays the time by moving a pointer along a linear scale shouldn’t be too hard. After all, steppers and linear drives should do the job in a jiffy. Throw an Arduino in and Bob’s your uncle, right?

Wrong. At least that’s not the way [Leo Fernekes] decided to build this unique ratcheting linear clock, a brilliant decision that made the project anything but run-of-the-mill. The idea has been kicking around in [Leo]’s head for years, and there it stayed until inspiration came in the unlikely form of [This Old Tony], one of our favorite YouTube machinists. [Old Tony] did a video on the simple genius of latching mechanisms, like the ones in retractable pens, and that served as an “A-ha!” moment for [Leo]. For a ratchet, he used a strip of bandsaw blade oriented so the teeth point upward. A complex bit of spring steel, bent to engage with the blade’s teeth, forms a pawl to keep the pointer moving upward until it reaches the top.

[Leo] decided early on that this would be an impulse clock, like the type used in schools and factories. He used a servo to jog a strip of tape upward once each minute; the tape is engaged by jaws that drag the pointer along with it, moving the pawl up the ratchet by one tooth and lifting the pointer one minute closer to the top. The pointer releases at the top and falls back to start the cycle over; to arrest its freefall, [Leo] had the genius idea of attaching magnets and using eddy currents induced in the aluminum frame for the job. Finished off with a 3D-printed Art Deco scale, the clock is a unique timepiece that’s anything but boring.

We really appreciate [Leo]’s unique and creative take on projects, and his range. Check out his everlasting continuity tester and his phage-like sentry gun for some neat build details.

source https://hackaday.com/2020/09/26/linear-clock-ratchets-up-the-action/

Fermenting Yogurt With The Help Of Hardware

Fermentation is a natural process that has been exploited by humanity for millennia. Behind such favorites as cheese and beer, it takes just the right conditions to get the desired results. To aid in this process, and to explore the crafts of their ancestors, [Victoria] and [Petar] created an electronic fermentation quilt.

Bulgarian yogurt was the tasty end result from this work.

Anyone familiar with breadmaking will be familiar with throwing a cloth over dough when left to rest. This is all about temperature management, providing optimum conditions for the yeast to work their magic. This fermentation quilt takes things to the next level, integrating soft heater pads and temperature sensing hardware into the fabric itself. Rather than acting as a simple insulator, the quilt can actively supply heat where needed, switching off when reaching the set temperature. In this example, the quilt is set to maintain a temperature of 45 degrees for the optimum production of Bulgarian yogurt.

The fermentation quilt serves as an excellent example of what can be achieved when combining textiles with smart electronics. Tools like Adafruit’s Lilypad and conductive thread all come together to make this a functional and useful device, and shows that electronic textiles aren’t just limited to blinky wearables.

Fermentation is a popular topic among hackers, with [Trent Fehl]’s Supercon talk at the 2019 Supercon covering similar ground from a sourdough perspective. It goes to show that hardware skills can pay off in the kitchen, too!

source https://hackaday.com/2020/09/26/fermenting-yogurt-with-the-help-of-hardware/

Internet Connected E-Paper Message Board

Are you still writing notes on paper and sticking them to the fridge like it’s the ’80s? Well, if you are, and you read this site, you’d probably like to upgrade to something a bit more 21st century. And, thanks to robot maker [James Bruton], you can leave your old, last century, message taking behind as he has a tutorial up showing you how to build an internet connected e-paper message display board. And, if you have a Raspberry Pi, an e-paper display and adapters just lying around doing nothing, then this project will cost you less than the buck that paper and a magnet will cost you.

Sarcasm aside, this is a pretty nice project. As mentioned, the base of this is a Raspberry Pi – [James] uses a Pi 4, but you could get away with an older, lower powered model as well. This powers the cheap(-ish) e-paper display he found online, which comes with the necessary adapters for the Pi, as well as a python library to write to the display. [James] uses a Google Sheet as the cloud storage for the message board, and there is some python code to access the cells in the Sheet and print them on the display if anything has changed. A cron job runs the script every 5 minutes to catch changes in the messages.

As with most of the projects that [James] does, he gives a good overview in the video and goes over the process of finding the hardware and writing and updating the script. He’s put the script and details as well as the CAD file for the frame he created for the project up on GitHub. [James] has been featured several times on the site before, check out some of his projects.

source https://hackaday.com/2020/09/25/internet-connected-e-paper-message-board/

Tracking Down Radio Frequency Noise Source, With Help from Mother Nature

Amateur radio operators and shortwave listeners have a common enemy: QRM, which is ham-speak for radio frequency interference caused by man-made sources. Indiscriminate, often broadband in nature, and annoying as hell, QRM spews forth from all kinds of sources, and can be difficult to locate and fix.

But [Emilio Ruiz], an operator from Mexico, got a little help from Mother Nature recently in his quest to lower his noise floor. Having suffered from a really annoying blast of RFI across wide swaths of the radio spectrum for months, a summer thunderstorm delivered a blessing in disguise: a power outage. Hooking his rig up to a battery — all good operators are ready to switch to battery power at a moment’s notice — he was greeted by blessed relief from all that noise. Whatever had caused the problem was obviously now offline.

Rather than waste the quiet time on searching down the culprit, [Emilio] worked the bands until the power returned, and with it the noise. He killed the main breaker in the house and found that the noise abated, leading him on a search of the premises with a portable shortwave receiver. The culprit? Unsurprisingly, it was a cheap laptop power supply. [Emilio] found that the switch-mode brick was spewing RFI over a 200-meter radius; a dissection revealed that the “ferrite beads” intended to suppress RFI emissions were in fact just molded plastic fakes, and that the cord they supposedly protected was completely unshielded.

We applaud [Emilio]’s sleuthing for the inspiration it gives to hunt down our own noise-floor raising sources. It kind of reminds us of a similar effort by [Josh (KI6NAZ)] a while back.

source https://hackaday.com/2020/09/25/tracking-down-radio-frequency-noise-source-with-help-from-mother-nature/

Building A Compact Reflow Oven With Halogen Lamps

Very often, particularly on the Internet, we’re fooled into thinking bigger is always better. The fact remains that this isn’t always the case. When it comes to reflow ovens, for example if you’re working with short runs of small PCBs, or if you just don’t have a lot of space in the workshop, a smaller oven will be more desirable than a large one. It’s factors like these that drove [Sergi Martínez]’s latest build.

Built inside a metal project case, first attempts involved using an off-the-shelf heating element, with poor results. The element had a high thermal inertia, and was designed for use in water, so didn’t last in the reflow application. Learning from the experience of others, [Sergi] switched to using halogen lamps, netting much greater success. An Arduino Nano is responsible for running the show, using firmware developed by [0xPIT]. There’s also a screen for monitoring reflow profiles, and a cooling fan to help keep temperature in the ideal zone.

It’s a tidy build that would be particularly useful for quickly running batches of small PCBs without the long wait times required to heat a larger oven. Energy efficiency should be better, too. Of course, if you’re a fan of the classic toaster oven builds, we’ve got those too. Video after the break.

source https://hackaday.com/2020/09/25/building-a-compact-reflow-oven-with-halogen-lamps/

Autodesk Blinks, Keeps STEP File Export in Free Version of Fusion 360

Good news, Fusion 360 fans — Autodesk just announced that they won’t be removing support for STEP file exports for personal use licensees of the popular CAD/CAM platform after all.

As we noted last week, Autodesk had announced major changes to the free-to-use license for Fusion 360. Most of the changes, like the elimination of simulations, rolling back of some CAM features, and removal of generative design tools didn’t amount to major workflow disruptions for many hobbyists who have embraced the platform. But the loss of certain export formats, most notably STEP files, was a bone of contention and the topic of heated discussion in the makerverse. Autodesk summed up the situation succinctly in their announcement, stating that the reversal was due to “unintended consequences for the hobbyist community.”

While this is great news, bear in mind that the other changes to the personal use license are still scheduled to go into effect on October 1, while the planned change to limit the number of active projects will go into effect in January 2021. So while Fusion 360 personal use licensees will still have STEP files, the loss of other export file formats like IGES and SAT are still planned.

source https://hackaday.com/2020/09/25/autodesk-blinks-keeps-step-file-export-in-free-version-of-fusion-360/

Road Pollution Doesn’t Just Come from Exhaust

Alumni from Innovation Design Engineering at Imperial College London and the Royal College of Art want to raise awareness of a road pollution source we rarely consider: tire wear. If you think about it, it is obvious. Our tires wear out, and that has to go somewhere, but what surprises us is how fast it happens. Single-use plastic is the most significant source of oceanic pollution, but tire microplastics are next on the naughty list. The team calls themselves The Tyre Collective, and they’re working on a device to collect tire particles at the source.

Tires become positively charged as you drive, like a Van De Graaff generator, so the team postulates that the most efficient way to collect the waste is to mount electrostatically charged plates where the plastics discharge. Road dust should pass through instead of gumming up the system since it is not charged. In an odd twist, hybrid vehicles are more dangerous regarding this type of pollution than their 100% petrol counterparts since they have to support a battery and electric motor.

When the tire dust is collected, it isn’t dumped out, because it can be reused as a pigment or even refined back into new tires. They’re collecting 60% of thrown particles in a lab setting, and they’re improving. What goes around comes around.

source https://hackaday.com/2020/09/25/road-pollution-doesnt-just-come-from-exhaust/

Ask Hackaday: Is Windows XP Source Code Leak a Bad Thing?

News comes overnight that the Windows XP source code has been leaked. The Verge says they have “verified the material as legitimate” and that the leak also includes Windows Server 2003 and some DOS and CE code as well. The thing is, it has now been more than six years since Microsoft dropped support for XP, does it really matter if the source code is made public?

The Poison Pill

As Erin Pinheiro pointed out in her excellent article on the Nintendo IP leak earlier this year (perhaps the best Joe Kim artwork of the year on that one, by the way), legitimate developers can’t really make use of leaked code since it opens them up to potential litigation. Microsoft has a formidable legal machine that would surely go after misuse of the code from a leak like this. Erin mentions in her article that just looking at the code is the danger zone for competitors.

Even if other software companies did look at the source code and implement their own improvements without crossing the legal line, how much is there still to gain? Surely companies with this kind of motivation would have reverse engineered the secret sauce of the long dead OS by now, right?

Spy vs. Spy

The next thing that comes to mind are the security implications. At the time of writing, statcount pegs Windows XP at a 0.82% market share which is still going to be a very large number of machines. Perhaps a better question to consider is what types of machines are still running it? I didn’t find any hard data to answer this question, however there are dedicated machines like MRIs that don’t have easy upgrade paths and still use the OS and there is an embedded version of XP that runs on point-of-sale, automated teller machines, set-top boxes, and other long-life hardware that are notorious for not being upgraded by their owners.

From both the whitehat and blackhat side, source code is a boon for chasing down vulnerabilities. Is there more to be gained by cracking the systems or submitting bug fixes? The OS is end of life, however Microsoft has shown that a big enough security threat still warrants a patch like they did with a remote desktop protocol vuln patch in May of 2019. I wonder if any of this code is still used in Windows 10, as that would make it a juicy tool for security researchers.

As for dangerous information in the leak, there have been some private keys found, like the NetMeeting root certificate. But its hard to say how much of a risk keys like this are due to the age of the software. You should stop using NetMeeting for high-security video conferencing if you haven’t already… it was end of life thirteen years ago so there’s nothing surprising there.

You Just Might Learn Something

I think the biggest news with a leak of code like this is the ability to learn from it. Why do people look at the source code of open source projects? Sure, you might be fixing a bug or adding a feature, but a lot times it’s to see how other coders are doing things. It’s the apprenticeship program of the digital age and having source code of long-dead projects both preserves how things were done for later research, and lets the curious superstars of tomorrow hone their skills at the shoulder of the masters.

Like a Museum Vouching for the Legitimacy of Artifacts

Why don’t company’s get out in front of this and publish end-of-life code as open source? This would vouch for the validity of the code. As it stands, how do you verify leaked code acquired from the more dimly lit corners of the Internet? Publishing the official source code for end of life projects preserves the history, something the Internet age has never given much thought to, but we should. We’ve heard the company promoting the message that Microsoft loves open source, here’s another great chance to show that by releasing the source code since it’s already out there from this leak. It would be a great step to do so now, and an even better one to take before leaks happen with future end of life products.

This is a pie-in-the-sky idea that we often trot out when we encounter stories of IoT companies that go out of business and brick their hardware on their way out. In those cases, the source code would allow users to roll their own back-end services that no longer exist, but Microsoft would be likely to frown on a “LibreWinXP” project based on their own code. It’s likely that the company still has a few long-term contracts to provide support for entities using XP hardware.

So What Do You Think?

This is Ask Hackaday so we want to know your take on this. When old source code leaks, is it a bad thing? Are there any compelling reasons for keeping the source code from projects that have seen their last sunset a secret? And now that the XP code is out there somewhere, what do you think may come for it? Weigh in below!

source https://hackaday.com/2020/09/25/ask-hackaday-is-windows-xp-source-code-leak-a-bad-thing/

Hackaday Podcast 086: News Overflow, Formula 1/3 Racer, Standing Up For Rubber Duckies, and Useless Machine Takes a Turn

Hackaday editors Elliot Williams take Mike Szczys peruse the world of hacks. There was so much news this week that we lead off the show with a rundown to catch you up. Yet there is still no shortage of hardware hacks, with prosthetic legs for your rubber ducky, a RC cart that channels the spirit of Formula 1, and a project that brings 80’s video conferencing hardware to Zoom. There’s phosphine gas on Venus and unlimited hacking projects inside your guitar. The week wouldn’t be complete without the joy of riffing on the most useless machine concept.

Take a look at the links below if you want to follow along, and as always, tell us what you think about this episode in the comments!

Direct download (~60 MB)

Places to follow Hackaday podcasts:

Episode 086 Show Notes:

New This Week:

Interesting Hacks of the Week:

Quick Hacks:

Can’t-Miss Articles:

source https://hackaday.com/2020/09/25/hackaday-podcast-086-news-overflow-formula-1-3-racer-standing-up-for-rubber-duckies-and-useless-machine-takes-a-turn/

Candy Slide Keeps Halloween Spooky and Socially Distant

Pandemic got you down about the prospects for Halloween this year? While you may not be able to do the Monster Mash with all your friends and family, there are plenty of ways to hand out candy while upholding social distancing practices. [WickedMakers] built a spooky six-foot candy slide to help keep their celebration in compliance with the CDC.

Their candy slide is almost entirely made of PVC, plus some gauze to mummify it and make it scarier. It’s essentially a six-foot long section of 3″ tubing supported by two ladders made of 1″ tubing that put the top four feet off the ground and a kid-friendly two feet off the ground at the receiving end. [WickedMakers] did a great job of hiding the PVC-ness of this build. We can’t help but wonder how much harder it would be to make the skeleton put the candy on the slide. Check out the build video after the break.

Need some Halloween headgear? You could always build N95 filter material into an EDM helm to hand out candy. Stay safe out there this year, and remember: always check your Halloween candy for malicious payloads.


source https://hackaday.com/2020/09/25/candy-slide-keeps-halloween-spooky-and-socially-distant/

This Week in Security: uTorrent Vulnerable, Crowd-Sourcing Your Fail2Ban, and Cryptographers at Casinos

The uTorrent client was recently updated to fix a null pointer dereference (CVE-2020-8437), discovered by [whtaguy]. Triggering the dereference simply crashes the client — so far an actual RCE hasn’t been found. Given the nature of the null pointer dereference, it’s possible this bug is limited to denial of service. That’s extremely good, because the flaw is extremely easy to target.

BitTorrent is a clever protocol. It’s still used to distribute large files, like Linux ISOs. The concept is simple: Split a large file into small chunks. Send the chunks to a client one at a time. As each chunk is received, the client sends a copy of that chunk to the next client. As a result of this peer-to-peer (p2p) arrangement, the bandwidth available to the server is greatly multiplied. As with all other p2p arrangements, the sticking point is how to make those connections between peers, particularly when most of the world’s desktops are behind NAT routers. In practice, for two peers to share data, at least one of them has to have a port opened or forwarded to the client. This is often accomplished through Universal Plug-n-Play (UPnP) or the NAT Port Mapping Protocol (NAT-PMP). The idea of both protocols are the same; a client on an internal device can request a temporary port forward without manual intervention. Whether it’s a good idea to allow automatic port forwards is another issue for another day.

BitTorrent uses a custom data serialization scheme, bencode, to include more complex data structures in both .torrent files, as well as the handshake sent between peers when connecting. Bencode can represent multiple data types, one of which being a dictionary type. Of interest here is that a dictionary can contain a dictionary as a value, and the protocol doesn’t specify a maximum depth. In the uTorrent client, this depth is tracked internally by using an integer as a bit field, essentially bit-shifting a binary 1 into this integer for each level of dictionary parsed. The bencode decoding code overflows the integer when more than 32 dictionaries are nested. This overflow results in an attempted access of a null pointer, crashing the client.

This vulnerable code can be targeted in two different ways. The first is through a specially crafted torrent file. This is rather uninteresting, as the client simply crashes when trying to open the file. The interesting vector is through peer handshakes. The malicious bencode data can be sent as a part of the handshake, crashing the client on the other end. This ability is intriguing, because it could be used in a targeted DoS attack against a specific torrent.

It’s been pointed out that a popular older version of uTorrent doesn’t have this exact vulnerability, though the normal caution about running outdated software still applies. It’s also possible that similar vulnerabilities could be found in other BitTorrent clients.

Crowd-Sourced Fail2ban

If you run a service connected to the internet, then you probably know a bit about fail2ban. It’s a daemon that watches your system logs for repeated events, like an attempt at guessing an SSH password, and temporarily blacklists the IP address making the guesses. It’s a handy tool, but wouldn’t it be even better if that live blacklist could be used on many systems at once? Crowdsec aims to be that solution. Once installed and opted-in, each event of interest is turned into a data point consisting of the IP, event type, and timestamp, and uploaded to the central database. From there, each report is then folded in to the continually evolving blacklist. The project is young, but this might be one to keep your eyes on.

When a Cryptographer Goes to the (Virtual) Casino

Our old friends, the NCC Group, took aim at a niche industry, online gambling. Specifically, they took a look at online roulette wheel gambling, but their techniques are widely applicable.

The first principle to understand is that the house always wins. To put it another way, the gambling establishment is guaranteed to make a profit. Understanding exactly how that works can be important. In the case of roulette, both types of wagers are stacked slightly towards the house. The margin is small enough that even a minor advantage can turn the tables. So, one of the easiest avenues to examine is the random number generator. Find the list of winning numbers, and see if some numbers actually come up more often. A quick trick the authors shared: represent the numbers as a bitmapped image. The human brain is exceptionally good at recognizing patterns when the data is displayed the right way.

Another possible weakness is how the close of betting is implemented. If a user could modify the site’s JS in the browser, he could send bets later than intended. If the server-side doesn’t carefully check for such an attack, late bets could give a player an edge. The entire write-up is full of interesting strategies, both for general web security research, as well as gambling and roulette specific strategies.

Bits and Bytes

Remember the botched AES implementation in Microsoft’s Active Directory? The US Cybersecurity and Infrastructure Security Agency (CISA) has deemed it a severe enough risk that any government systems that haven’t been patched (as of the 22nd), are to be permanently disconnected from government networks.

Drupal just released an update that addresses a cross-site scripting (XSS) vulnerability. An XSS attack is one where one user can inject some JavaScript into a website, and it runs when other users view the impacted page. (The Samy worm on Myspace being the prime example.) There isn’t much additional detail available at this time, but this problem is in Drupal core, rather than a 3rd party plugin, so the impact is potentially quite wide. Go dust off those Drupal installs, and get them updated!

source https://hackaday.com/2020/09/25/this-week-in-security-utorrent-vulnerable-crowd-sourcing-your-fail2ban-and-cryptographers-at-casinos/

Hacking A Cheap Action Cam Into A Dashcam With A Microcontroller

Repurposing commodity electronics is one of the true forms of hacking, and it’s always the simple little hacks that lead to big ones. [Everett] wanted to use a $20 GoPro clone as a dash cam, so he wired a microcontroller into it to automate some actions and make it practical.

The camera turns on automatically when connected to external power like a car charger, but starting and stopping a recording and power down all had to be done manually. [Everett] wanted to automate these functions, so he opened up the camera and started probing with an oscilloscope. He found the power button, record button, 3.3 V and external 5 V traces conveniently next to each other in the top of the camera.

To automate the required functions, he wired in a PIC10 on a small breakout board, powered by the 3.3 V line. It detects if 5 V is connected to the charging port on start-up via an N-channel FET, then automatically starts a recording. When the 5 V power is switched off with the car, it waits 10 seconds before stopping the recording and switching off the camera. If no external 5 V is not detected on start-up the microcontroller does nothing, which allows the camera to be used as a normal handheld. [Everett] mounted the camera to his rearview mirror with a magnetic bracket made using a combination of a 3D printer and 3D pen.

This is a simple and practical little hack, and the firmware is available on Github. Cheap dashcams are available for similar prices, but you won’t get any hacking satisfaction that way.

The very nature of actions cameras inspire hacking. You can simply add an external battery with the help of a 3D printer, or go all out and build a gimballed helmet cam from scratch

source https://hackaday.com/2020/09/25/hacking-a-cheap-action-cam-into-a-dashcam-with-a-microcontroller/

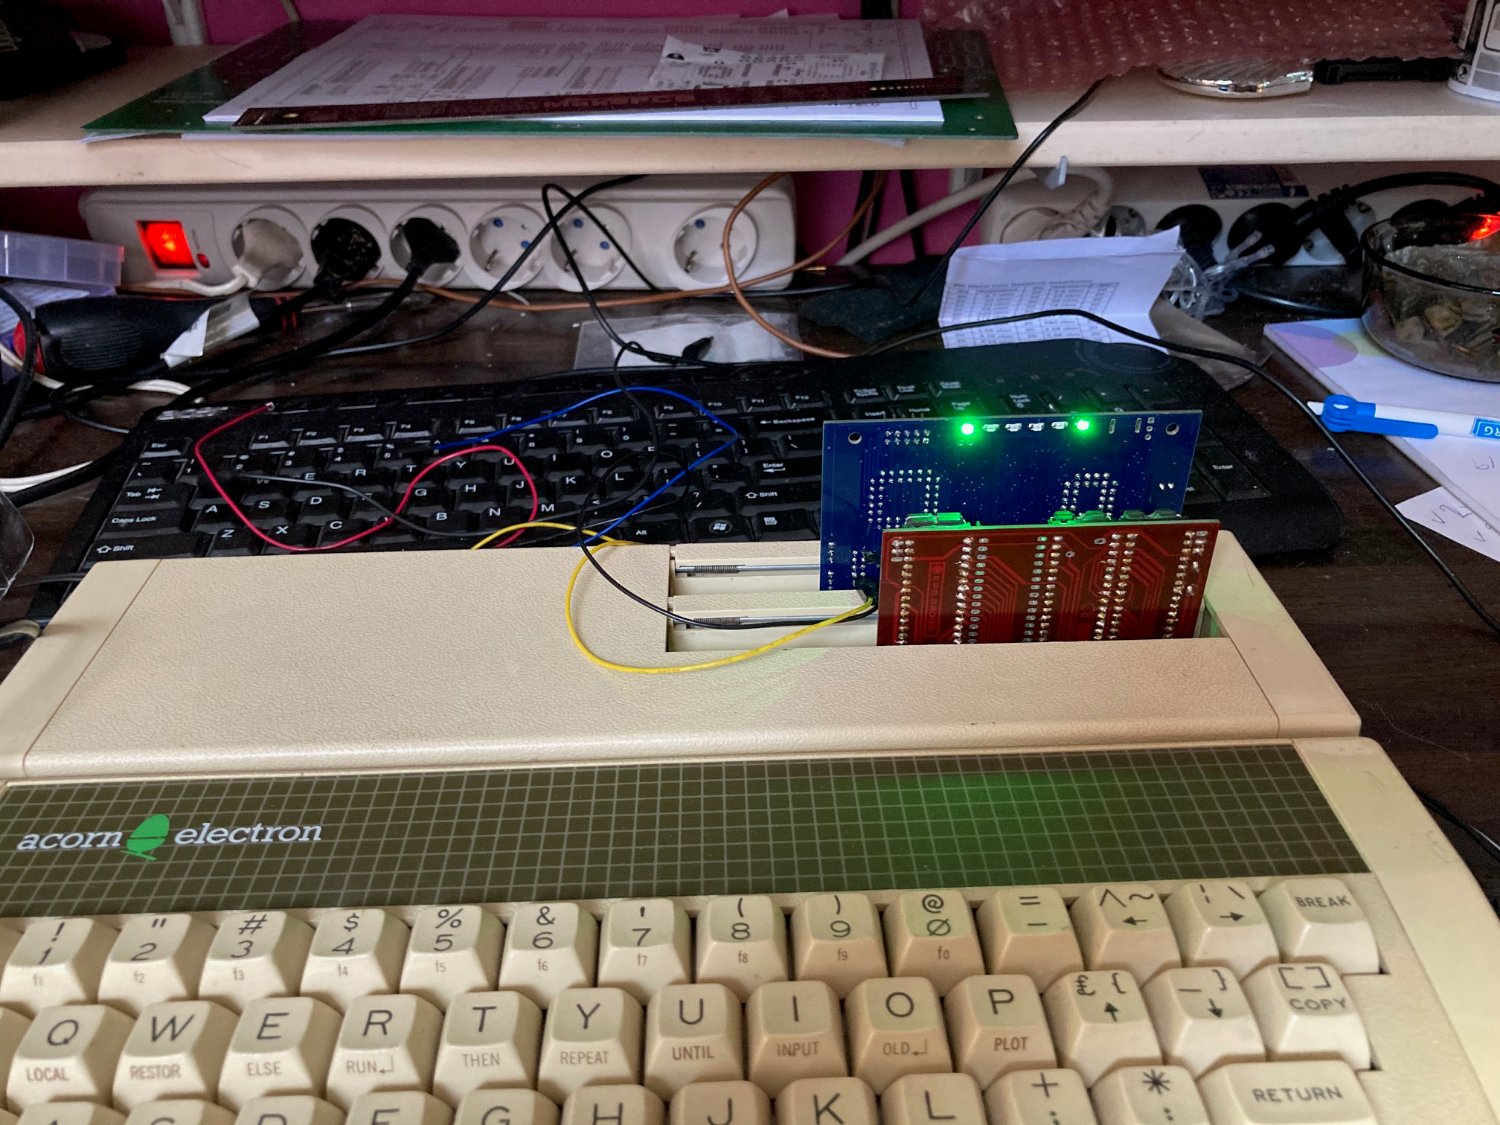
Adding WiFi To The Acorn Electron

In the continuing quest by countless hobbyists to allow every 1980s 8-bit home computer to experience the joys of an online experience that doesn’t involve a 9600 baud modem, [Roland Leurs] has created a cartridge-based module for the Acorn Electron that adds WiFi, which he showed off at the virtual ABug conference in September 2020.

The Acorn Electron is a Synertek 6502-based computer that was released in the UK in August of 1983. It’s a budget version of the well-known BBC Micro educational/home computer, with 32 kB of RAM and featuring BBC BASIC v2 in its ROM. [Roland]’s ElkWiFi card slots into an available cartridge slot, after which the onboard ESP8266 (ESP-1 module) can be enabled and used as a WiFi modem.

Acorn Electron with Plus 1 expansion, ElkWiFi and additional expansion card inserted.

The board features the Exar ST16C2552CJ dual UART chip, one channel of which connects to the ESP-1 module, with the other channel used as an uncommitted UART header. The control logic is implemented in VHDL and flashed to the onboard Xilinx CPLD, and a 128 kB RAM module is used as WiFi data buffer.

Although a definite niche product, reading through the forum thread makes one really appreciate the technical complexity and joy once things are beginning to work reliably. It also shows one of the few cases where an ESP-1 module is used for its original purpose: as an easy way to add WiFi functionality with full WiFi and TCP stack, without burdening the main CPU.

(Thanks, BaldPower)

source https://hackaday.com/2020/09/25/adding-wifi-to-the-acorn-electron/

DIY Grout Cleaning Machine Does A Good Job

Cleaning tiled floors can be a drag. Getting the tiles themselves clean is bad enough, but often dealing with the grouted joints in between requires more elbow grease and attention to detail. It’s a tedious chore, and thus one ripe for improvement. [Elite Worm]’s cleaning machine is an excellent solution to the problem.

The machine is built entirely from scratch, using primarily 3D printed components. A fluid tank is fitted to the chassis, along with a custom 3D-printed pump run by a DC motor, to deliver cleaning product where its needed. A large DC motor is then used to spin a nylon brush which gets deep in the tile grooves to clean out the grime. The chassis is then fitted with rollers to allow it to glide along the floor. Finally, a handle is fitted which allows the user to push the tool along, with switches to turn on the spinning brush and dispense cleaning fluid.

It’s a great tool, and one which eliminates hours of scrubbing on hands and knees. We’re sure the time investment in the build will pay off before long. We’ve seen other tricky cleaning hacks before, too. Video after the break.

source https://hackaday.com/2020/09/24/diy-grout-cleaning-machine-does-a-good-job/